Preface
In many software companies, for a long time, Bug count has been regarded as an intuitive metric for measuring quality and team performance.
But in reality, using Bug count as a performance metric, a seemingly simple and direct way of measuring, actually has fundamental flaws. It not only fails to reflect the real value of individuals and teams, but also gives rise to the “Cobra effect”, hindering the team from moving toward genuine quality goals.
In this article, we will analyze in depth the drawbacks of using Bug count as a performance metric, and explore more reasonable ways of measuring.
Fundamental Drawbacks of the “Bug Count” Metric
Taking defect count as a single indicator of performance assessment essentially reduces the complex, multi-dimensional goal of quality to a single, quantifiable number.
Such simplification creates a fatal gap between actual measurement and expectation, thereby fundamentally violating the purpose of software engineering.
The Cobra Effect
Any single, quantified data metric, once it becomes a performance measure, tends to trigger negative results contrary to its original design intent, giving rise to the Cobra Effect
The Cobra Effect originated in India during British rule. To control the cobra population, the government offered a bounty for killing them, but local residents began breeding cobras artificially to collect the bounty. When the government stopped the bounty, the released cobras caused an even worse infestation.
In the software development process, obsessive metrics like Bug count can likewise produce outcomes that backfire.
For the testing team, this way of measuring gives rise to the typical problem of “valuing quantity over quality”. To meet a “defect quota” or performance target, testers tend to waste precious time looking for minor issues that have low impact and low priority but are easy to find, just to “pad the numbers”. As a result, a great deal of development and business resources are wasted.
Beyond that, when the goal focuses on quantity, testers tend to stop doing in-depth analysis of Bugs, that is, they stop pursuing high-value Bug reports (see the previous article 【】). So this kind of metric design actually punishes those testers committed to providing high-value insights.
For the development team, if a developer’s performance is tied to the “number of bugs fixed”, they have more incentive to fix the “small and beautiful”, easy-to-solve bugs rather than tackle a high-value, complex, deep-seated fault. It may even lead to “producing and consuming one’s own”, where they actively create easy-to-fix defects just to meet the fix-count/fix-rate metric.
So it is clear that the result ultimately driven by the metric runs counter to real value.
Ignoring the Essence of Quality Goals
In my previous article 【】 I analyzed in depth the real purpose of engaging in software testing. One important point is:
Software testing is not for finding Bugs
But this metric explicitly sets finding Bugs as the purpose of the testing work.
The purpose of testing is to accurately present the quality status of the product. And the overall quality status is unknown; pursuing Bug count will inevitably make testers invest more energy in the superficial, easy-to-trigger parts that are not critical to the system, while neglecting the parts that require in-depth analysis and more comprehensive exploration.
In other words, this metric actually encourages shallow testing but punishes deep testing.
And under this orientation, “shift-left testing” actually becomes empty talk; the greater the contribution of shift-left, the fewer Bugs are found later. It even hinders improvements in team efficiency and knowledge sharing within the testing team.
Creating Team Conflict and Destroying Psychological Safety
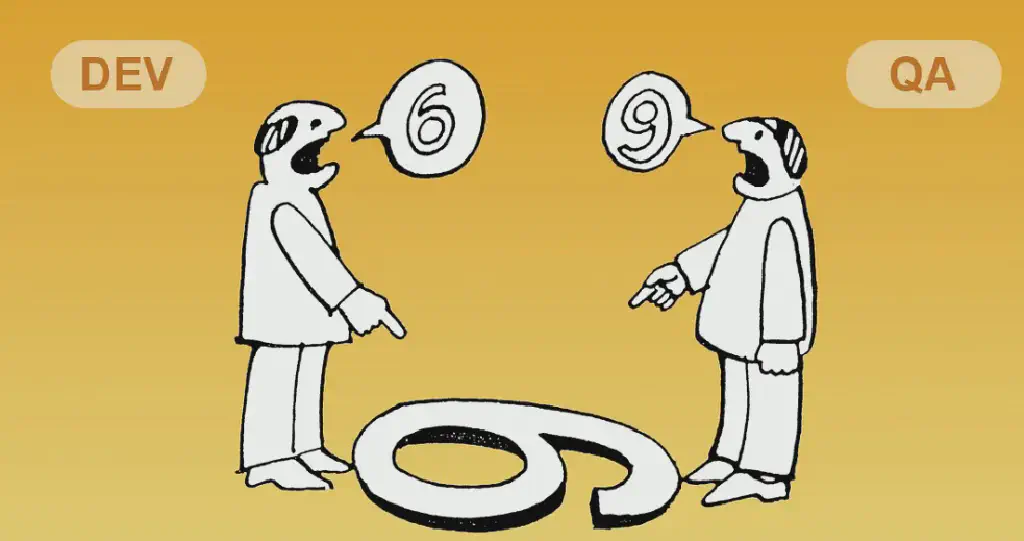
Establishing this metric also creates an opposition of “Tester vs Developer”, thereby destroying the cornerstone of a high-performing team - psychological safety.
Psychological safety means team members can freely express ideas, take risks, and admit mistakes without fear of negative consequences.
But when testers are incentivized to report more Bugs while developers are expected to produce as few Bugs as possible, the inevitable result is developers questioning whether a Bug is just the tester “padding the numbers”, and testers believing developers are merely making excuses to reduce the Bug count.
Such a metric creates a “culture of blame”. The trust relationship between the two teams naturally breaks down.
Building Value-Oriented Quality Measurement
Since “Bug count” is clearly unsuitable for performance measurement, and quality, as a black box, is indeed hard to measure fully accurately, here we can establish a value-oriented quality measurement system from the following aspects.
Product Quality Dimension
First, for the product itself and delivery quality, consider the following metrics:
(1) Customer and User Experience Metrics
Customer-reported functional defects: Compared with Bugs found internally, problems reported by customers better reflect real quality impact. But priority should be given to high-severity issues (such as functional failure, data loss) rather than simple counting.
Customer Satisfaction (CSAT) and Net Promoter Score (NPS): Directly obtain users’ evaluation of software quality through regular surveys; this is the most direct quality feedback.
(2) System Stability and Performance Metrics
System availability (Uptime): Measure normal uptime as a percentage, e.g. 99.9% availability means allowed downtime of no more than 43.2 minutes per month.
Performance metrics: Including page load time, API response time, transaction throughput, etc., directly reflecting the user experience.
Deployment success rate: Measures the reliability of the release process; a high success rate means a stable release process and fewer deployment-induced problems.
Online failure rate: Counts the number of failures occurring in the production environment, prioritizing high-severity failures that affect users.
(3) Problem Response and Fix Efficiency
Average time from problem identification to fix release: Measures the team’s response speed to problems; the shorter the time, the higher the fix efficiency.
Bug fix success rate: Counts the proportion of fixes that do not introduce new problems, reflecting fix quality.
Proportion of support tickets that need no escalation to developers: Measures the support team’s ability to solve problems independently; a higher proportion means a more stable system and better documentation.
Process Quality Dimension
Quality is not something the testing or development team can be responsible for alone; to improve quality, we must consider the whole process. For example:
(1) Code and Process Quality
- Code review cycle time: The average time from code submission to completed review; the shorter the time, the higher the collaboration efficiency.
- Test coverage trend: Focus on the growth trend of coverage rather than the absolute percentage, reflecting the continuous improvement of the testing system.
- Technical debt cleanup ratio: Counts the proportion of planned technical debt resolved, reflecting the team’s emphasis on long-term quality.
(2) Team Health
- Sprint goal success rate: Measures the team’s plan execution ability; a high success rate means reasonable goal setting and efficient team collaboration.
- Team member satisfaction: Understand team morale and job satisfaction through regular anonymous surveys; high satisfaction is the foundation of a high-performing team.
- Number of process improvement suggestions: Counts the number of process optimization suggestions raised by the team, reflecting the team’s awareness of continuous improvement.
Business Value Dimension
Quality ultimately serves business value; considering this aspect:
(1) Feature Delivery Quality
Proportion of features requiring hotfix: Counts the proportion of new features that need emergency fixes after release; a lower proportion means higher development quality.
Number of support tickets after new feature release: Measures user acceptance of and problem feedback on new features; fewer tickets means higher feature quality.
(2) Long-term Impact
Velocity trend: Observe the trend of the team’s development velocity; low-quality code causes velocity to gradually decline, while high-quality code maintains a stable velocity.
System maintainability and scalability assessment: Through architecture reviews, code complexity analysis, and other means, regularly evaluate the long-term health of the system.
Through this set of metrics, we should be able to measure the question “How good is the product quality actually?” fairly comprehensively.
Conclusion
Through the analysis above, we have examined why Bug count should not be used as a team performance metric; it can be said to do a hundred harms and no good.
At the same time, we have given a multi-dimensional, value-oriented quality metric system that measures team quality more comprehensively and scientifically from the dimensions of product quality, process quality, and business value.
Of course, there is no perfect metric system; every measurement has its limitations. The key is to maintain an open mind, regularly review and adjust the metrics, and avoid “metric dependency”. As the quality master W. Edwards Deming said, Quality is not determined by metrics, but by culture and systems.